Repository navigation
Error message 'Dataset row count exceeded the maximum count of 2146435071' in Fit() method #5751
Closed as not planned
Description

System information
- Windows10 Home:
- .NET Version 2.1.0:
- ML.NET Version 1.5.5:
Issue
- We are currently dealing with large sizes of data.
Is it possible to include a record size larger than INTMAX in the size of training data?
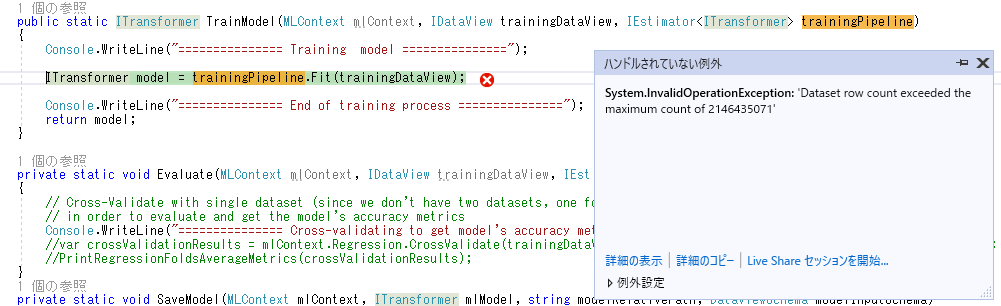
Source code / logs
    public static void CreateModel1()
    {
        // Load Data
        IDataView trainingDataView = mlContext.Data.LoadFromTextFile<ModelInput>(
                                        path: USDJPY_CSV_FILEPATH,
                                        hasHeader: true,
                                        separatorChar: ',',
                                        allowQuoting: true,
                                        allowSparse: false);

        // Build training pipeline
        IEstimator<ITransformer> trainingPipeline = BuildTrainingPipeline(mlContext);

        // Evaluate quality of Model
        Evaluate(mlContext, trainingDataView, trainingPipeline);

        // Train Model
        ITransformer mlModel = TrainModel(mlContext, trainingDataView, trainingPipeline);

        // Save model
        SaveModel(mlContext, mlModel, MODEL_FILEPATH, trainingDataView.Schema);


    }
    public static IEstimator<ITransformer> BuildTrainingPipeline(MLContext mlContext)
    {
        // Data process configuration with pipeline data transformations
        var dataProcessPipeline = mlContext.Transforms.Categorical.OneHotHashEncoding(new[] { new InputOutputColumnPair("period", "period") })
                                  .Append(mlContext.Transforms.Concatenate("Features", new[] { "period", "st_price", "volume" }));

        // Set the training algorithm
        var trainer = mlContext.Regression.Trainers.LightGbm(labelColumnName: "ed_price", featureColumnName: "Features");
        var trainingPipeline = dataProcessPipeline.Append(trainer);

        return trainingPipeline;
    }

    public static ITransformer TrainModel(MLContext mlContext, IDataView trainingDataView, IEstimator<ITransformer> trainingPipeline)
    {
        Console.WriteLine("=============== Training  model ===============");

        ITransformer model = trainingPipeline.Fit(trainingDataView);

        Console.WriteLine("=============== End of training process ===============");
        return model;
    }

    private static void Evaluate(MLContext mlContext, IDataView trainingDataView, IEstimator<ITransformer> trainingPipeline)
    {
        // Cross-Validate with single dataset (since we don't have two datasets, one for training and for evaluate)
        // in order to evaluate and get the model's accuracy metrics
        Console.WriteLine("=============== Cross-validating to get model's accuracy metrics ===============");
        //var crossValidationResults = mlContext.Regression.CrossValidate(trainingDataView, trainingPipeline, numberOfFolds: 5, labelColumnName: "ed_price");
        //PrintRegressionFoldsAverageMetrics(crossValidationResults);
    }
Activity
matouskozak commentedon Oct 23, 2026
Triage: I believe this limitation is present also in the upstream LigthGBM so only fixing this in ML.NET wouldn't resolve the issue. I would recommend to train on a representative subset, time window, or aggregation to limit the dataset size.